 Anil Motwani
- 19th Oct 2026
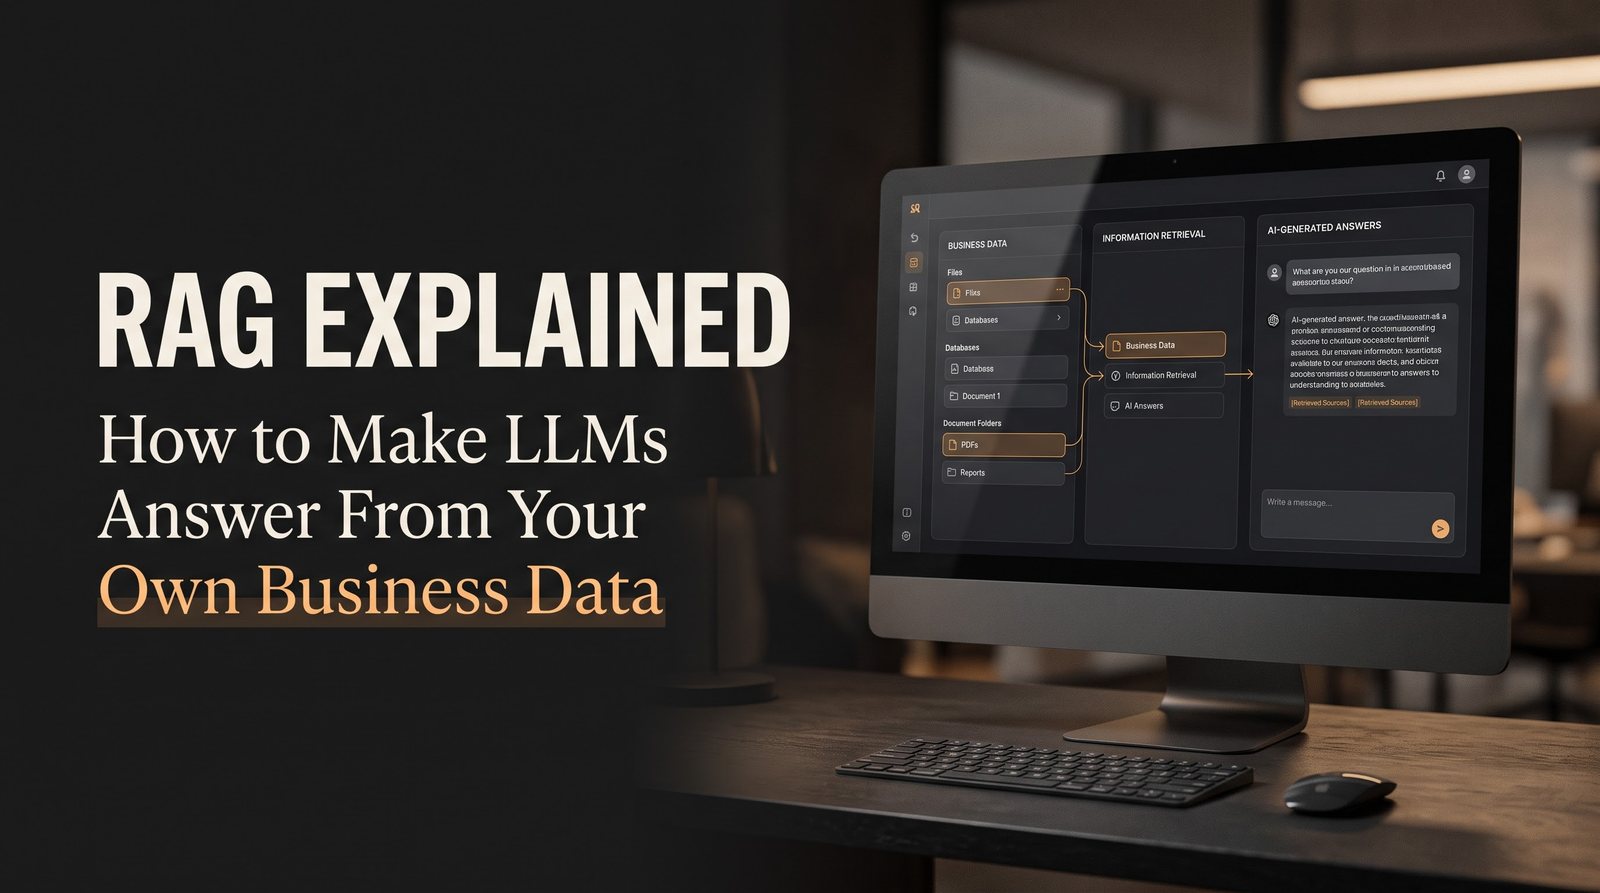
Large language models are impressive, but out of the box they only know what they were trained on. Ask a general model about your pricing, your HR policy or last month's product update and it will either refuse or, worse, confidently make something up. Retrieval-Augmented Generation (RAG) fixes this by fetching the right pieces of your own content first and giving them to the model as context for every answer.
A RAG pipeline has two halves. First, your documents (PDFs, help articles, SOPs, database records) are split into chunks, converted into embeddings and stored in a vector database. Then, when a user asks a question, the system searches that index for the most relevant chunks and sends them to the LLM along with the question. The model writes its answer from that material and can cite the exact sources it used, which makes the output easier to trust and to audit.
RAG doesn't make the model smarter. It makes the model better informed, and for business use that is usually what matters.
What It Takes to Build a Reliable RAG System
- Clean, well-structured source content with clear ownership
- Smart chunking and embeddings tuned to your type of documents
- Hybrid search (keyword + vector) with re-ranking for better accuracy
- Source citations and guardrails so the model says "I don't know" when it should
- Role-based access so users only retrieve data they are allowed to see
- Evaluation sets and monitoring to measure answer quality over time
RAG is the fastest way to turn an LLM into a useful assistant for your team or customers without the cost of training a custom model. Because the knowledge lives in your own index, updating it is as simple as adding or editing a document. Whether it powers an internal knowledge assistant, a support bot or a sales co-pilot, a well-built RAG system gives you accurate, source-backed answers grounded in your business data.
